Dashboard
Workspace
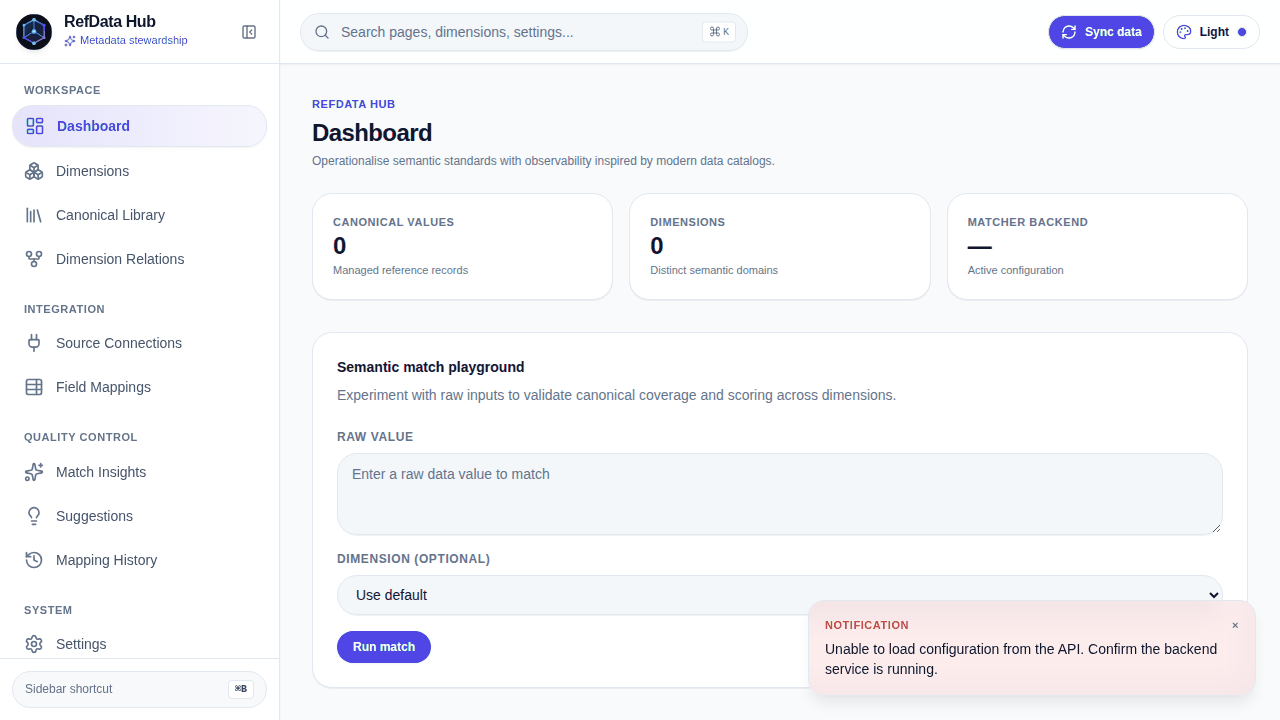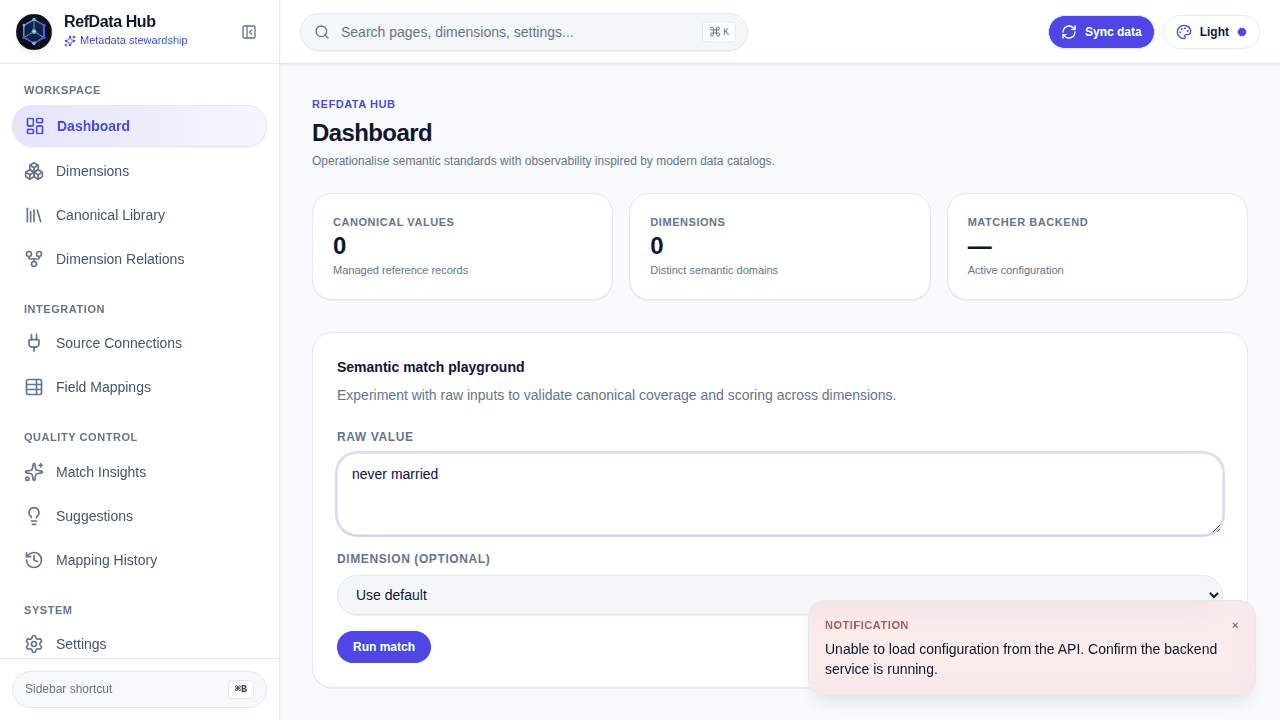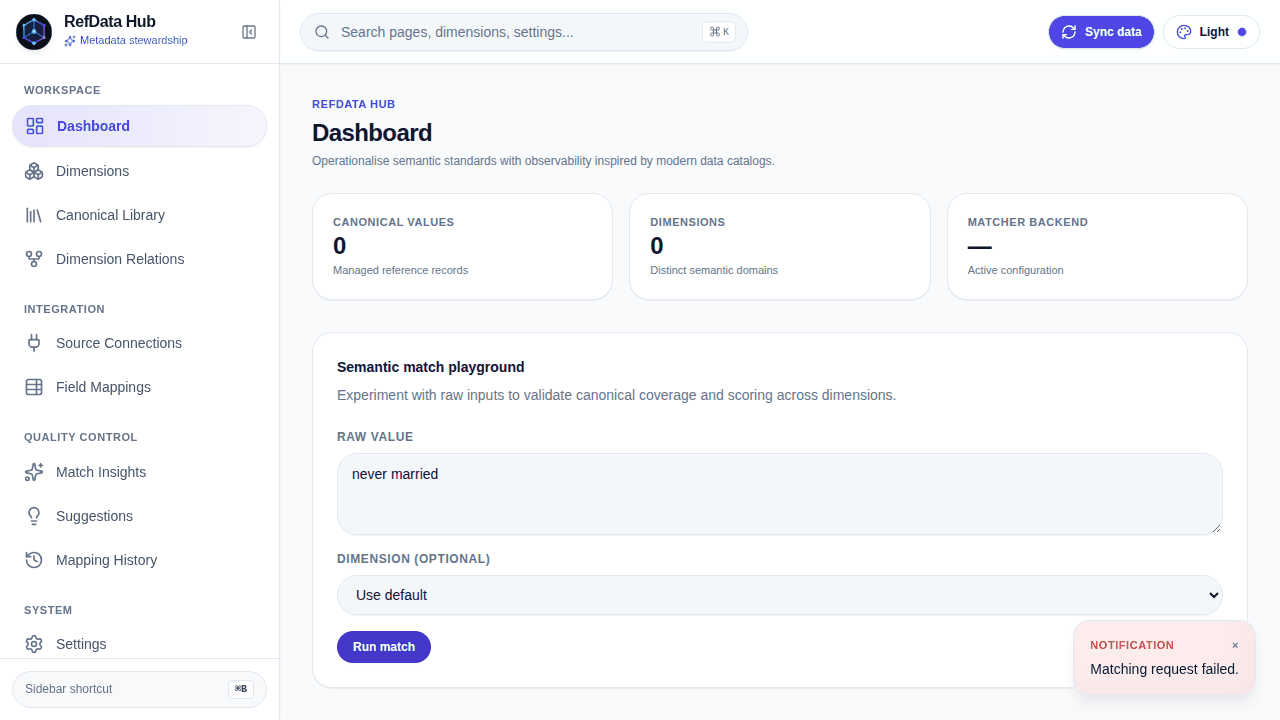
Operationalise semantic standards with observability inspired by modern data catalogs. The Dashboard is the landing page of the reviewer console and the fastest way to sanity-check that the matcher is behaving before you commit to a batch of review work.
What the dashboard shows
Three metric tiles read live from the app state context:
| Tile | Source | What it tells you |
|---|---|---|
| Canonical values | GET /api/reference/canonical |
Size of your approved golden-record set |
| Dimensions | GET /api/reference/dimensions |
How many semantic domains you have defined |
| Matcher backend | GET /api/config |
Whether matching runs on embeddings, lexical fallback, or LLM |
If the Matcher backend tile disagrees with what you set in
Settings, your most recent PUT /api/config did not persist.
Check that the API accepted the write and that the browser can reach it.
Semantic match playground
The playground is the fastest feedback loop in the product. Enter a raw value you expect to see in a source system, optionally pick a dimension, and see the ranked candidates immediately.
curl -X POST http://localhost:8000/api/reference/propose \
  -H 'Content-Type: application/json' \
  -d '{"raw_text": "Never married", "dimension": "marital_status"}'
The response carries a matches array of MatchCandidate objects, each with a
score between 0.0 and 1.0, ranked best-first:
{
  "raw_text": "Never married",
  "dimension": "marital_status",
  "matches": [
    {
      "canonical_id": 3,
      "canonical_label": "Unmarried",
      "dimension": "marital_status",
      "score": 0.94,
      "description": "Never married, single, no legal partner"
    }
  ]
}
The UI renders this as a table of label, dimension, description, and confidence percentage.
Read the score, not just the rank
A high score means the embedding put the candidate close to your raw text. It does not mean the candidate is correct. The score is a ranking signal for humans; approval is always a deliberate act.
Interpreting a weak match
| Symptom | Likely cause | Fix |
|---|---|---|
| Every score is low and flat | Embedding model has not downloaded, or the backend fell back to lexical matching | Check the Matcher backend tile and the API log for model download errors |
| A candidate from the wrong dimension ranks first | You left dimension unset, so the matcher searched the whole library |
Pin the dimension in the playground |
| Good candidates exist but scores are below the threshold | match_threshold is set too high for your data |
Lower it in Settings, or approve from Suggestions |
Next steps
-
Canonical Library
Curate the golden records the playground is matching against.
-
Suggestions
Work through the queue the dashboard's scores feed into.
-
Settings
Tune thresholds, the embedding model, and LLM escalation.